Around May, I made a tool called Obsidian-vault-mcp
This is a Codex plug-in for realizing two-way linkage between zotero, MinerU and Obsidian.
Articles can be found in previous issues Obsidian-vault-mcp introduction
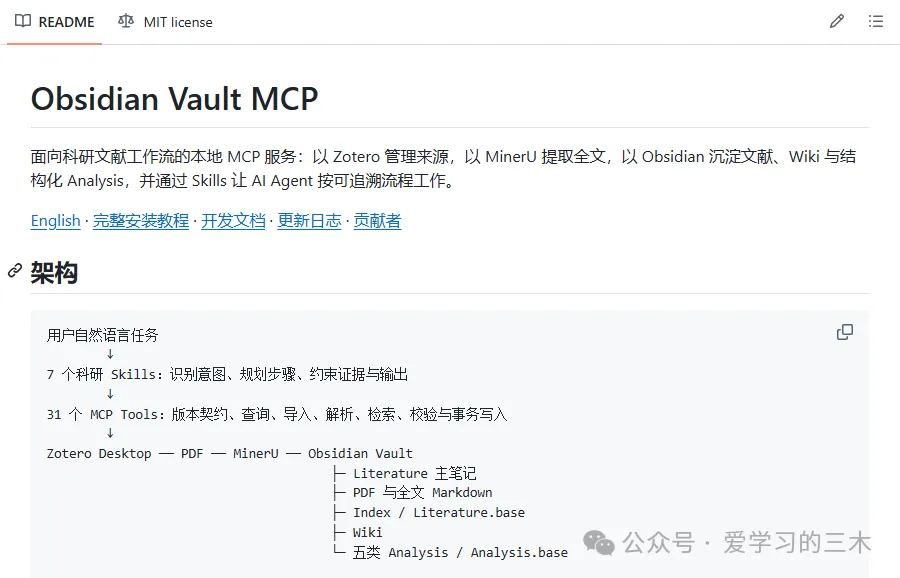
However, after thinking about it for a long time, I feel that this tool is too heavy now.
And it is mainly used by Agents. The file naming method is not the standard year + author + title.
If you simply let Agents manage it, it is just giving your second brain to an AI tool.
If I want AI to interpret a picture or a paragraph of a certain document, it would be inconvenient to use my previous tool.
Although there are already 87 stars, considering that I also want to add custom configuration functions, pdf2zh, scientific research drawing and many other needs in the future, it will be very troublesome to directly reconstruct the project system.
Therefore, I decided to start another project to make a multi-source scientific research tool
The implementation uses zotero as the source, MinerU as the analysis medium, and Obsidian as the carrier. A large number of scientific research tools are added in the middle to serve the database calling and computing interfaces required by most science majors, scientific research drawing calling interfaces (such as OpenAI, nano banana), and literature patent library API interfaces (such as semantic Scholar, Google scholar)
This project is the open source project I want to introduce below: omnischolar
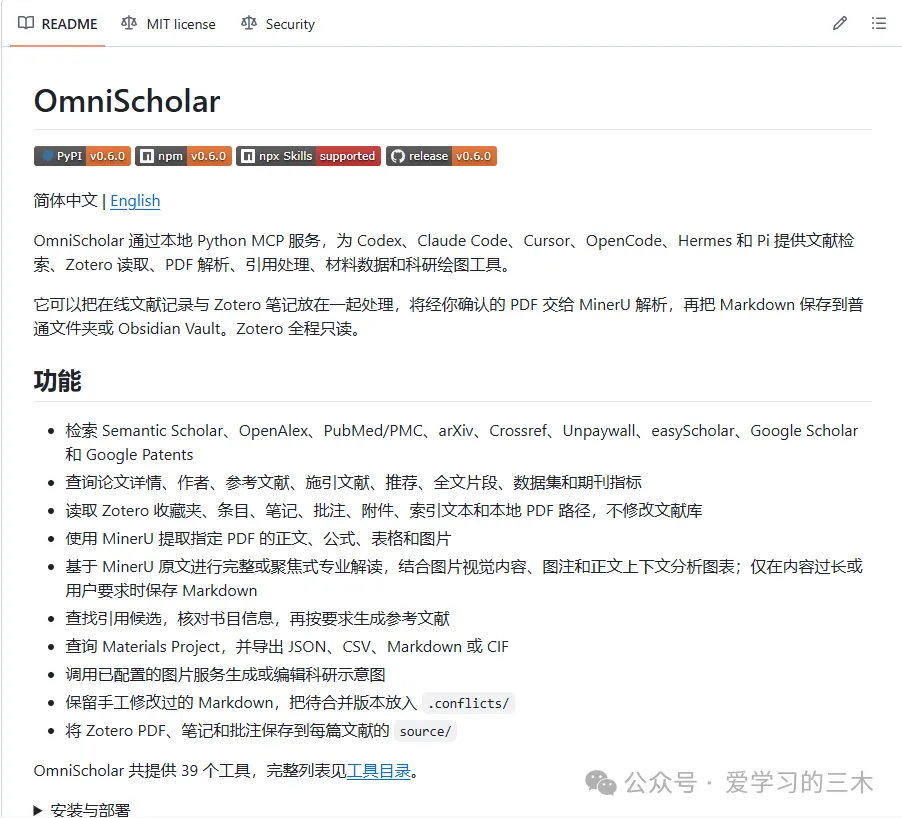
Project address: (Click to read the original text to jump)
Codex, CC, WorkBuddy, Cursor, Pi and other Agents can be used
Installation requires just a few commands:
Codex installation and update:
How to use?
Just send your request directly
For example:
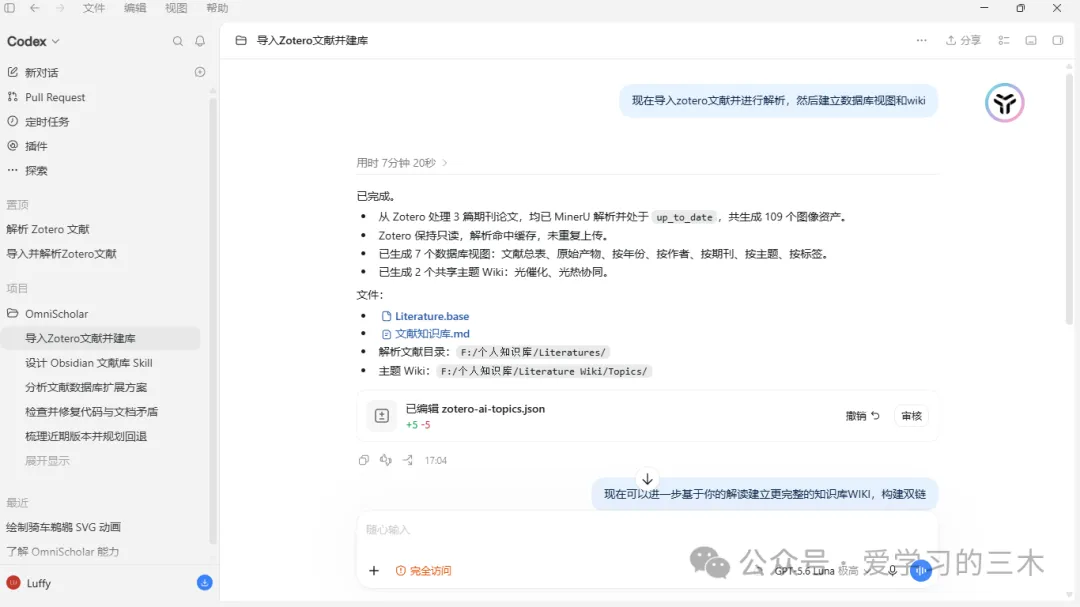
Then the MinerU API will be called to parse the document and save it as a markdown file.
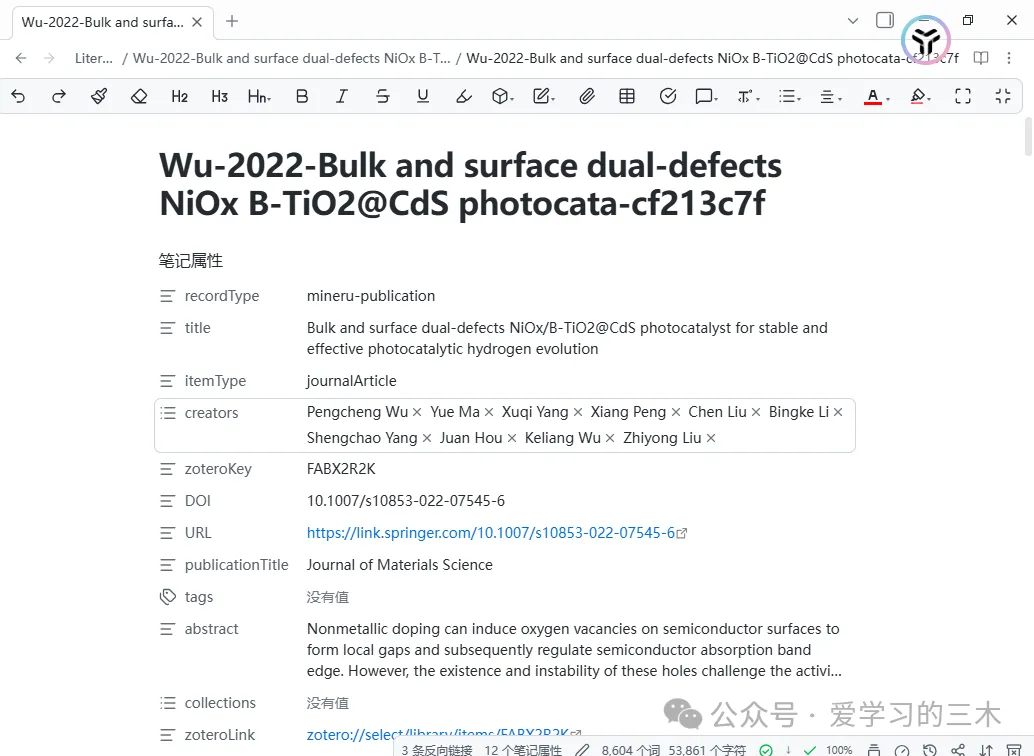
The parsed markdown file has frontmatter, which protects zotero metadata such as title, author, DOI, etc. Click zotero-link to jump back to zotero entries
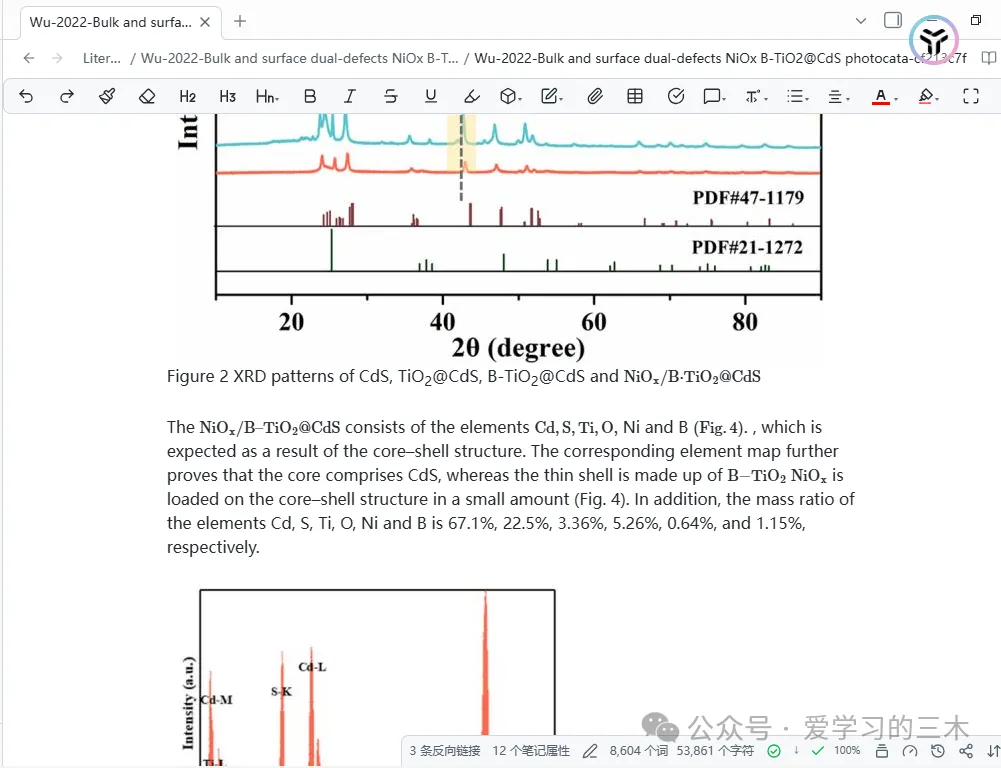
All chart formulas are basically saved losslessly, and pictures can be previewed directly
Use callout card folding for the wiki index of each document
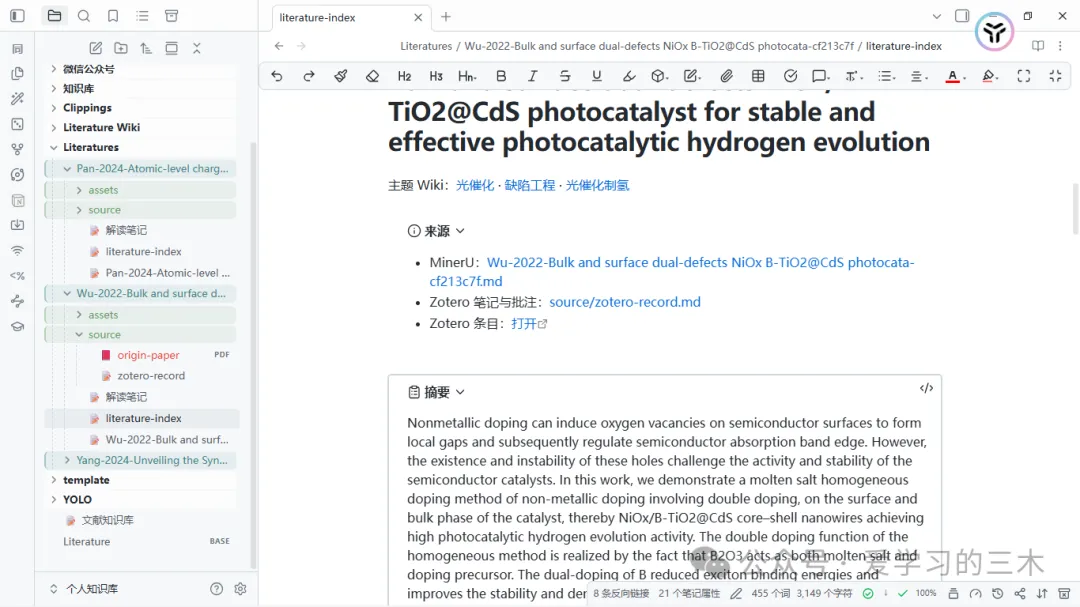
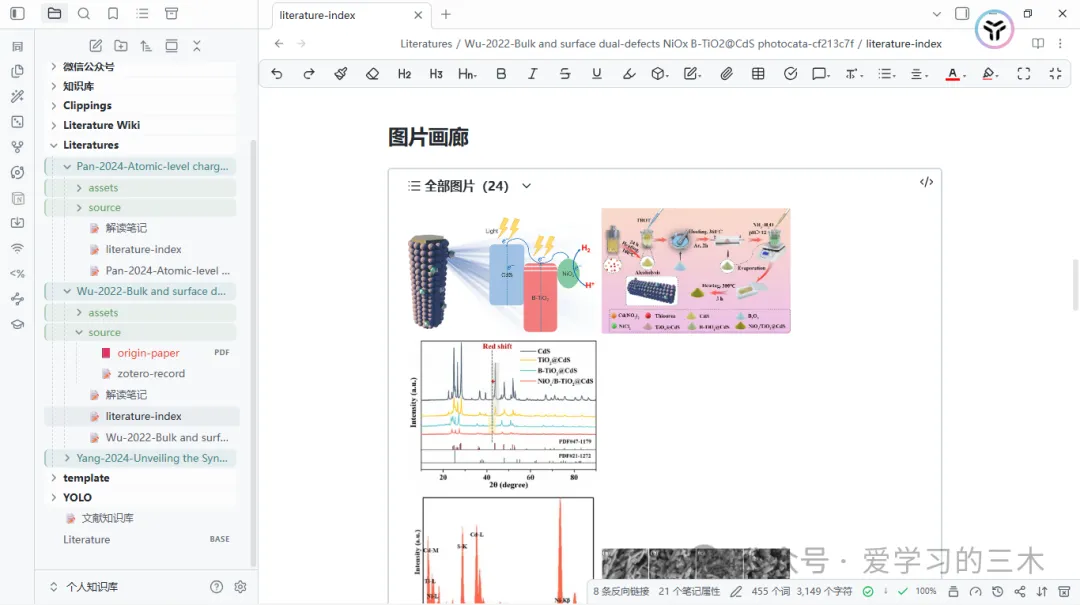
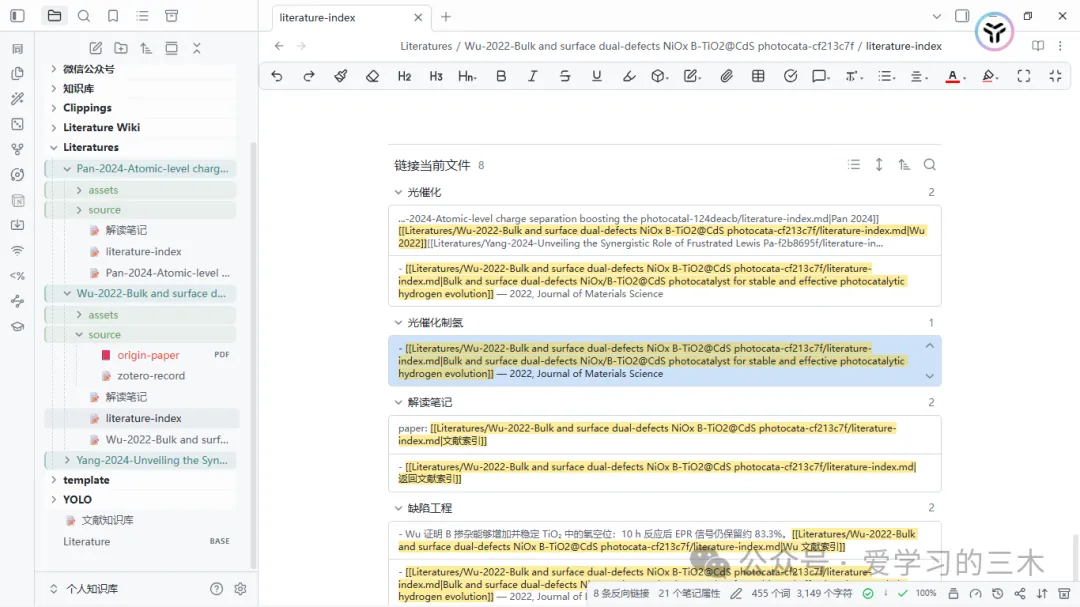
After intensive reading by the Agent, a self-growing knowledge system is established and classified according to different topics.
Notes can be clicked to jump in both directions.
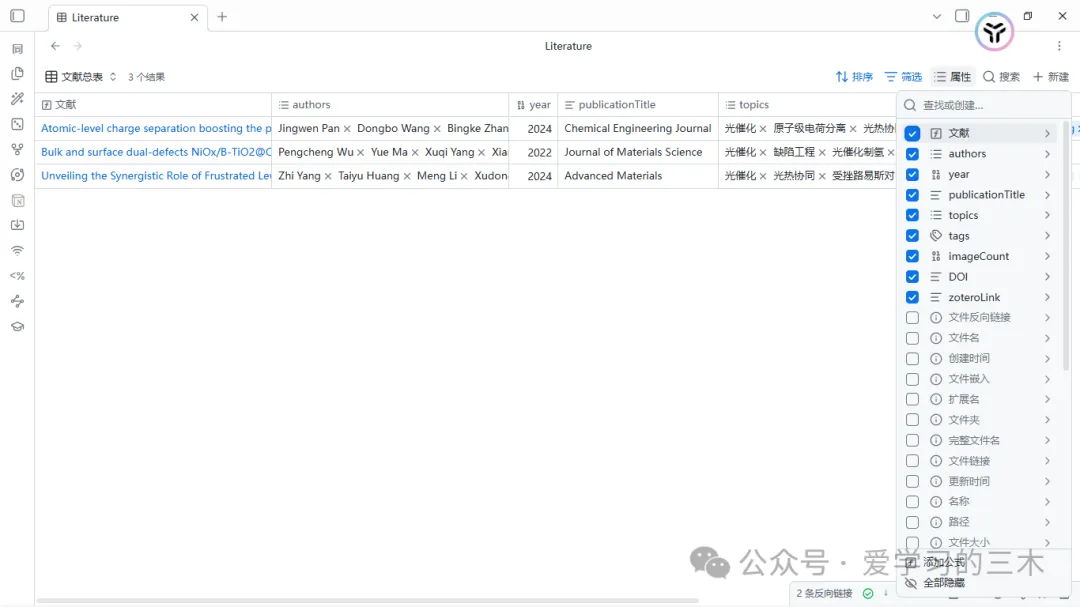
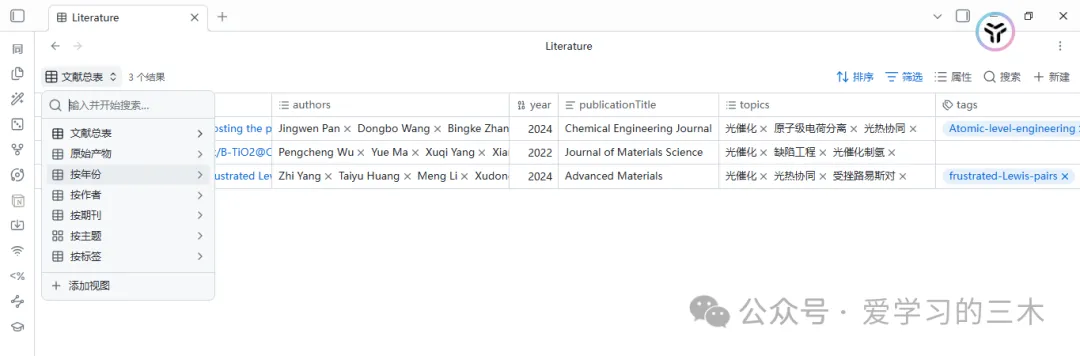
Then a database will be automatically generated to manage and review literature according to different views.
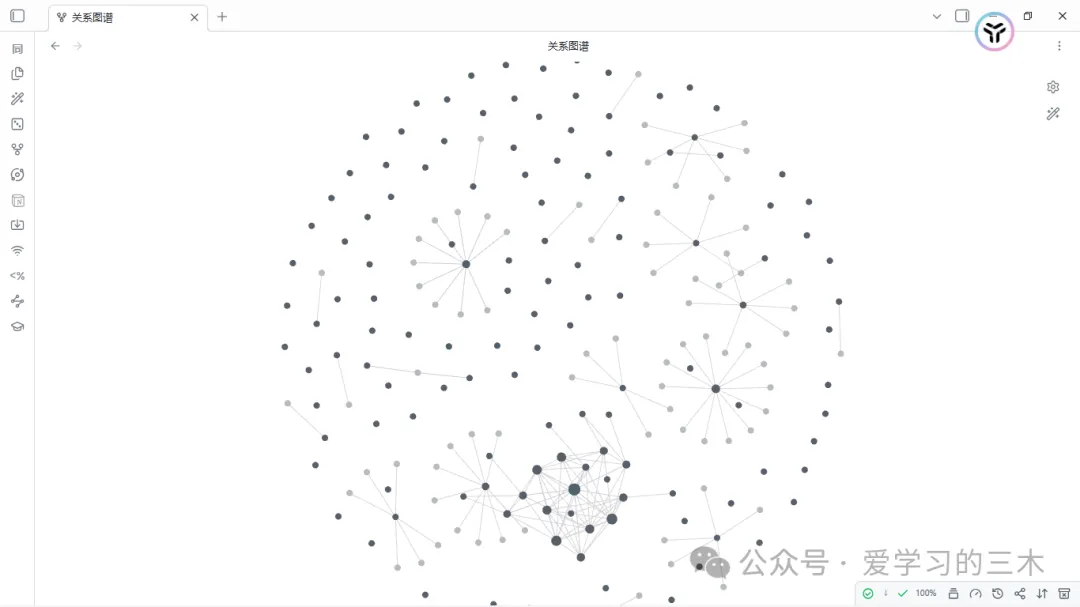
Then form the knowledge graph yourself
For the complete effect, you can watch the video demonstration below👇
In addition, this is just a basic function. My project also has built-in scientific research drawing SKILL and API calling tools. You only need to fill in the unified configuration file omnischolar.config.json and configure it.
If this is your first time, enter the following command in your terminal after installation to quickly configure:
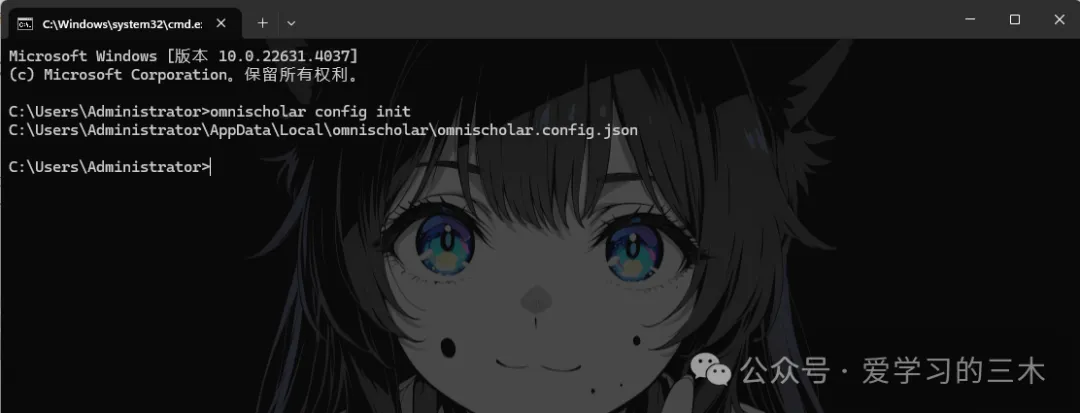
Then find the location of your configuration file, use an IDE code editor such as vscode to fill in your API-key and you can use it
Note that if you want to put all output files into Obsidian, you need to change this at the end of the configuration file to the file address of your Obsidian vault.
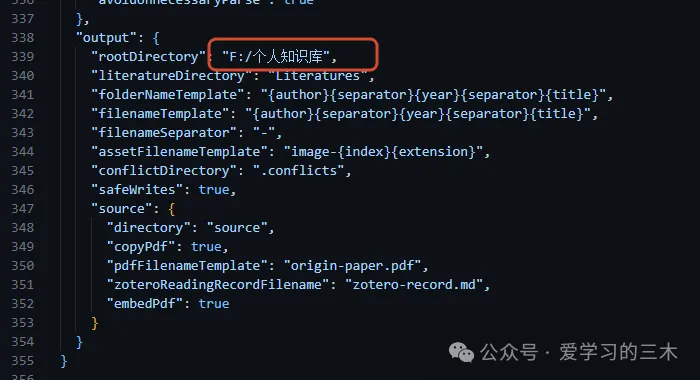
Then the MinerU API must be configured, otherwise it will not be able to have complete analysis of the chart.
Please see the official website for how to apply:https://mineru.net/apiManage/docs
Please fill in this after you get MinerU
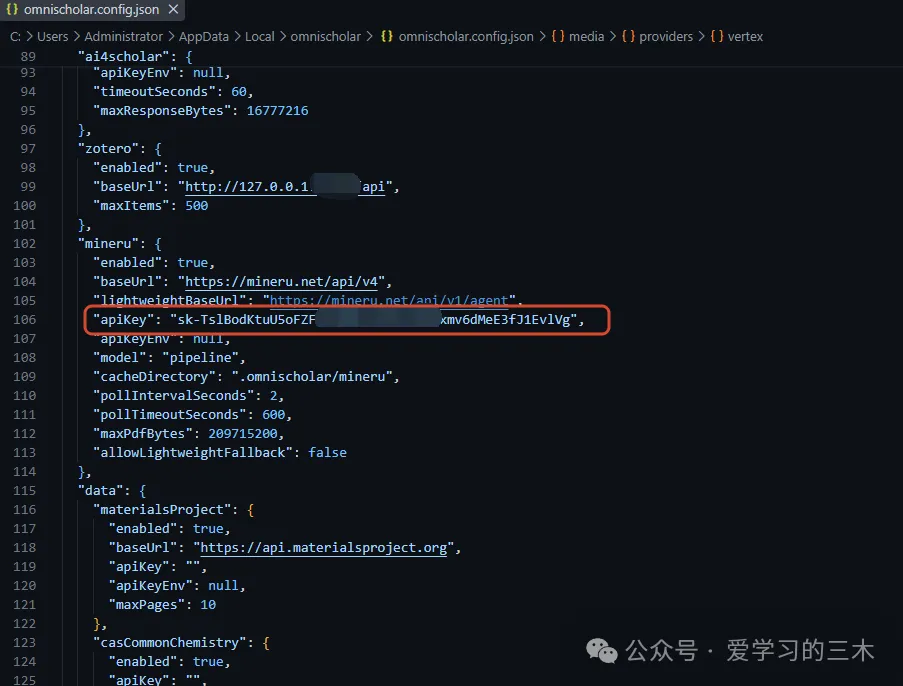
The configuration also includes third-party interfaces for scientific research drawing such as OpenAI, Gemini, Fal, atlas, etc.
There are also database interfaces such as material project, PubMed, and semantic scholar.
You can apply for and fill in the information yourself.
Remember to restart the Codex after configuring it.
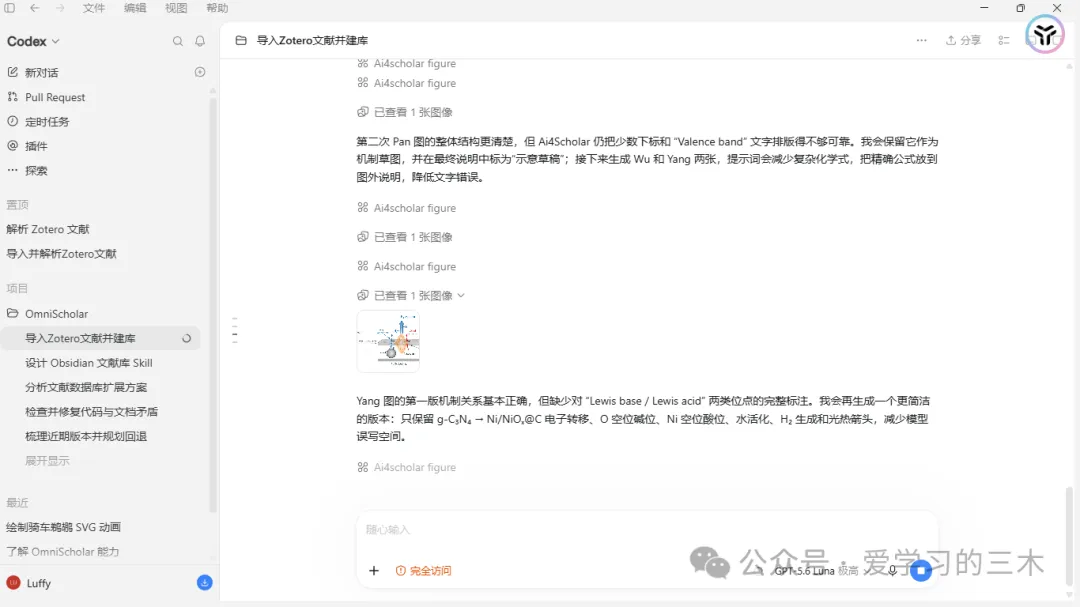
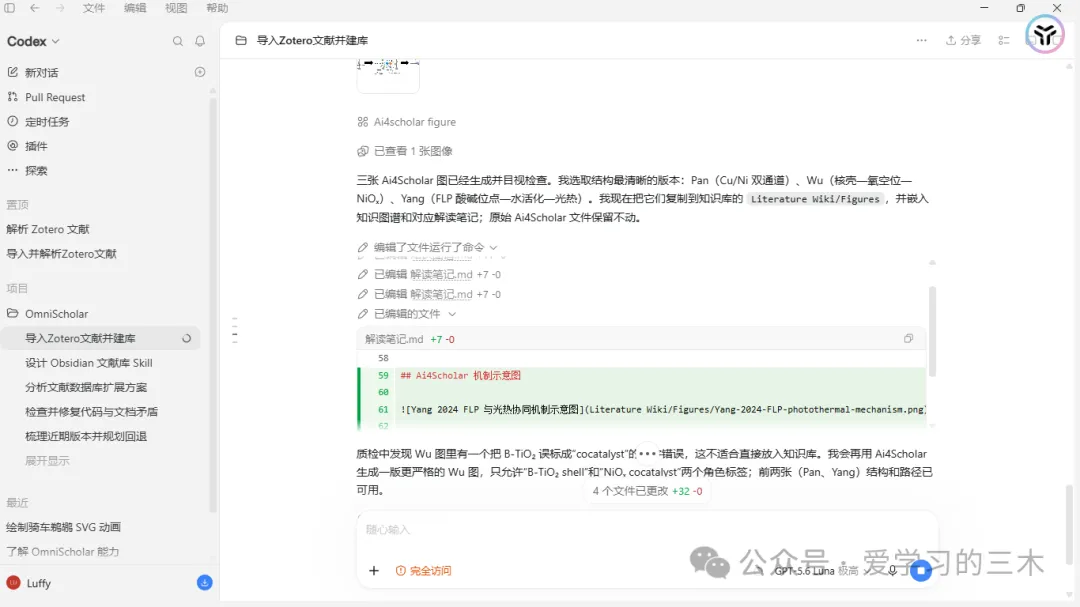
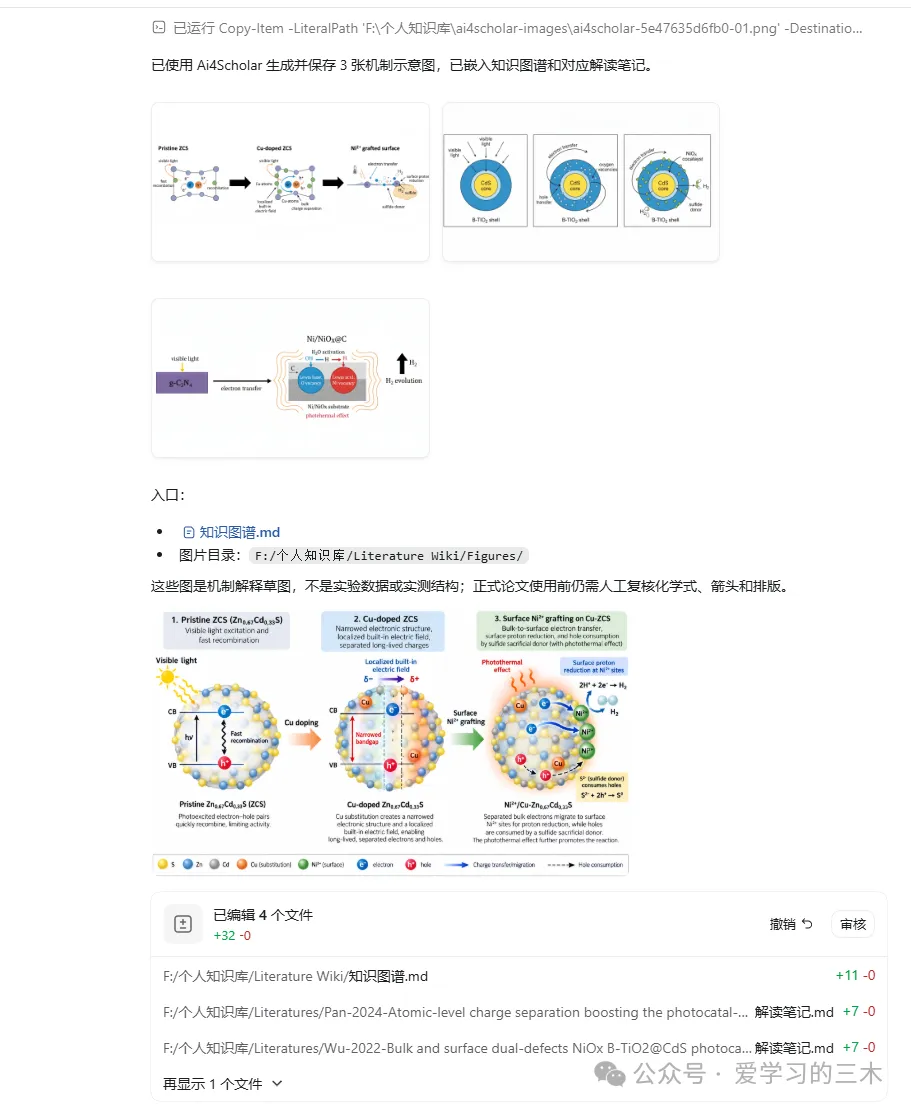
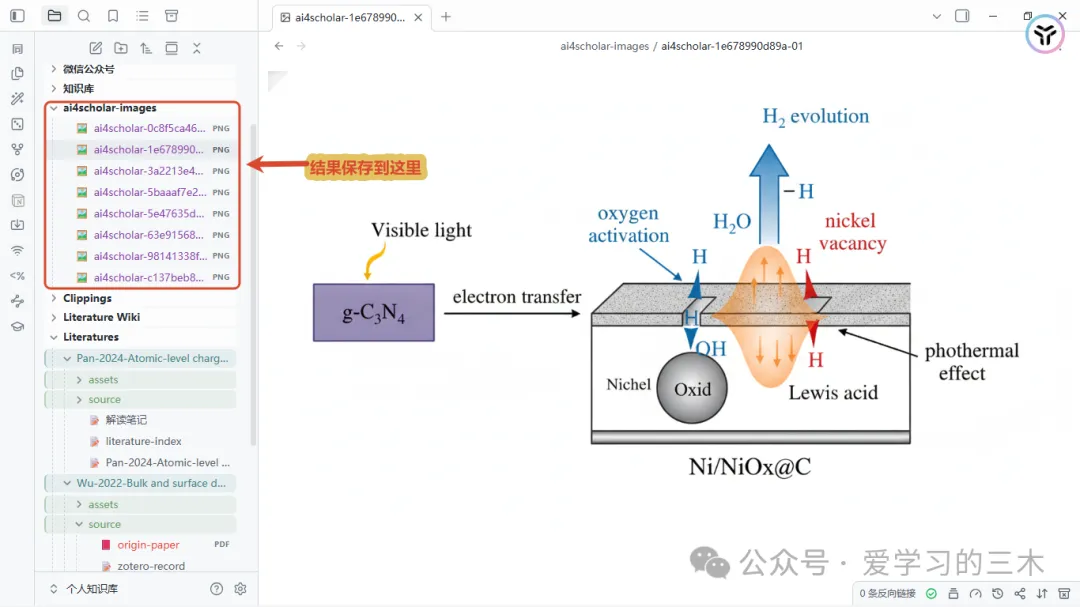
Here is a demonstration of using scientific research drawing:
It will automatically perform quality inspection and control until it meets the paper standards.
will also automatically trigger wiki updates
Another use is literature search:
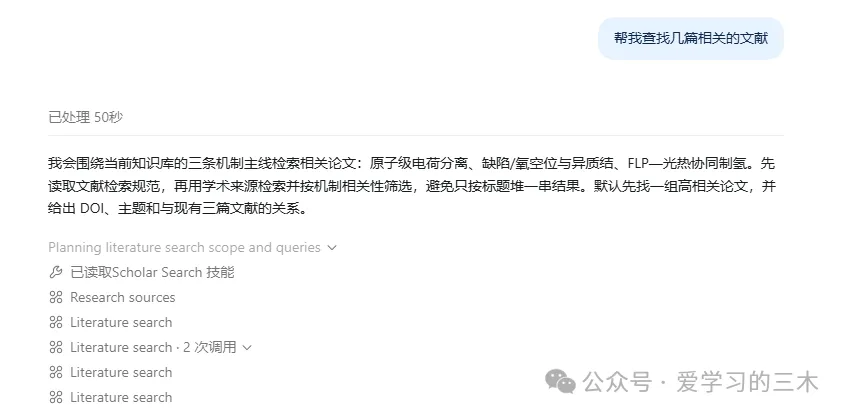
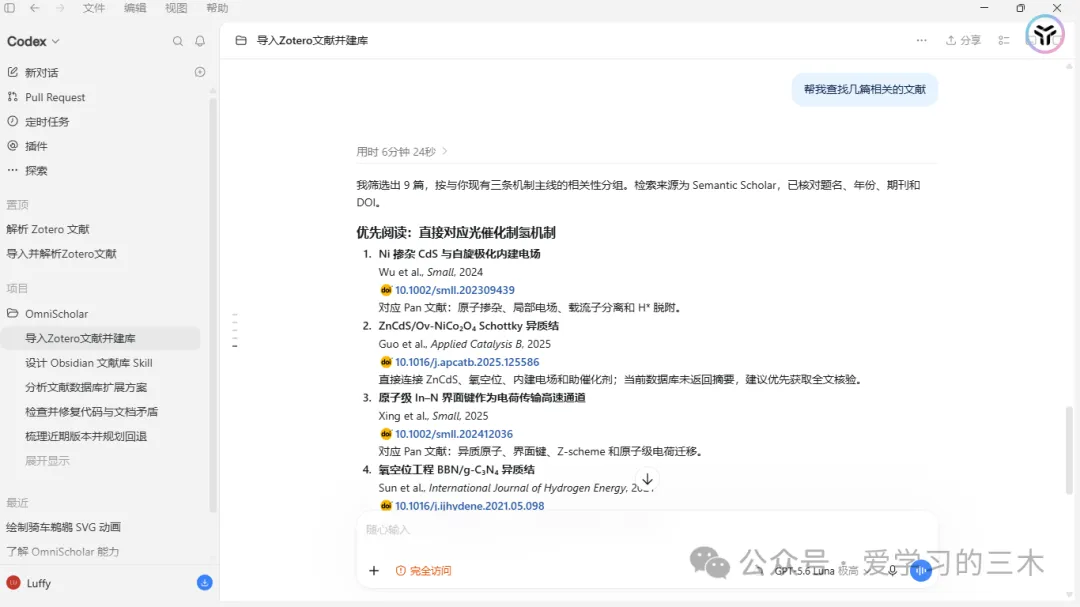
After completion, you will be asked whether you allow writing these documents to Zotero or Wiki; and you will be deduplicated, imported, parsed PDF, and then connected to the existing knowledge graph.
If you have installed the scansci-pdf project, you can download relevant documents in the closed source field in batches, and use it with the super-autonomous Astra to independently control the computer to complete document retrieval, download, analysis, and reconstruction of the wiki -> search for relevant documents -> document retrieval, achieving a closed loop
Of course, there are many functions in this project that I want to develop and access, such as adding a SKILL to call your local pdf2zh for batch translation of documents.
There are also crystal calculations, chemical formula analysis, and map analysis, which can all be implemented by accessing the API.
Tsk, tsk, tsk, there are so many good things I want to do.
But I think this is enough
In the future, the model will be powerful enough that it will not even require any tools. These processes will be abstracted into a concept and your intentions will be automatically recognized, and SKILL will no longer be needed to standardize any process!
-----All I wanna tell has been done-----
Thank you for your support along the way. I never thought that anyone would actually use a gadget developed by a non-major undergraduate student.
I am also very grateful for everyone's support and likes. The space is limited, so I will show two recent large pictures. Hehehe
Hey~
I’ve been really busy lately. I’m a junior in college and have a lot of homework to do in professional courses.
I basically only have time to develop this project at 1 or 2 o'clock in the evening, so I have been holding back the ultimate move for a long time and only released it now.
If you think it is helpful to you, you can support it on GitHub hehehe
At the end, write down some of my personal feelings:
Perhaps in another 2 or 3 years, the era of AGI and RSI will arrive, and AI will become as popular as the Internet today. Everyone knows about Codex and CC.
Everyone will use Agent tools, so the information gap has long become worthless.
What are we competing for? Is it execution? Cognition? experience?
No, I don’t think so.
I think it’s about always maintaining a curious and lifelong learning mentality.
Since 2022, no – probably earlier
The world is undergoing a technological explosion quietly, which has huge repercussions on the world at every moment.
Technology changes so fast that MCP, which I learned for less than half a month, was immediately updated to SKILL.
SKILL in turn pointed to the loop loop and later the DeepSeek harness
I think that without curiosity and the courage to learn, the opportunities buried around may have disappeared.
Where is the next opportunity, the next good fortune? I'm not sure, I don't know, and I don't need to know
Because the skills you keep practicing will come in handy one day
Enjoy the moment, my friends!
- Author:Sanmu
- URL:https://luffysite.top/article/omnischolar-01
- Copyright:All articles in this blog, except for special statements, adopt BY-NC-SA agreement. Please indicate the source!
Relate Posts